Why Server Logs Are the Untapped Gold Mine of Technical SEO
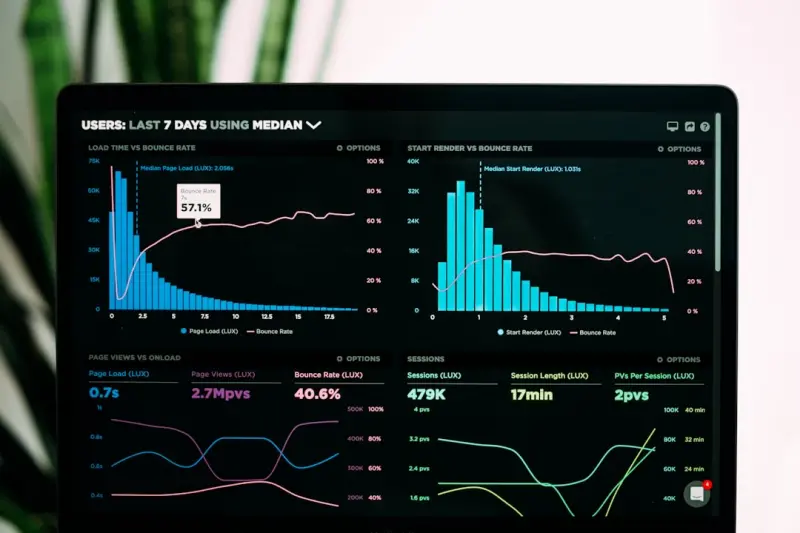
When most SEO teams talk about “technical SEO,” the conversation quickly gravitates toward Core Web Vitals, schema markup, or crawl‑budget tweaks. While those tactics are essential, they’re often driven by what we can see in the UI—Google Search Console, Lighthouse reports, or third‑party dashboards. What if I told you that the real, unfiltered pulse of your site lives in a place most marketers rarely visit: the raw server logs?
Server logs capture every request your web server processes—bots crawling your pages, users loading assets, and even the occasional 404 that slipped under the radar. By mining this data, you gain a backstage pass to Googlebot’s behavior, spot hidden inefficiencies, and make data‑driven decisions that directly impact rankings.
Getting Started: Collecting the Right Logs
The first step is simple: decide which logs you’ll analyze. Most modern web stacks produce two primary types:
- Access logs – Record every HTTP request, including IP address, timestamp, HTTP method, response code, user‑agent, and bytes transferred.
- Error logs – Capture server‑side errors (500s, timeouts, misconfigurations) that can cripple SEO performance.
For SaaS platforms running behind load balancers or CDNs, you’ll often need to aggregate logs from multiple nodes. Tools like Amazon CloudWatch Logs, Google Cloud Logging, or ELK Stack (Elasticsearch, Logstash, Kibana) make it easy to centralize and query logs at scale.
Decoding Bots: Who’s Crawling and What Are They Doing?
Not all bots are created equal. Googlebot, Bingbot, and the emerging LLM‑Powered Search crawlers each have distinct patterns. By filtering logs by user‑agent, you can answer critical questions:
- Which sections of your site receive the most crawl attention?
- Are there orphaned pages that Google never sees?
- How frequently does Googlebot revisit high‑value content?
These insights often reveal a mismatch between your internal linking strategy and how search engines actually discover your pages—a classic cause of wasted crawl budget.
Spotting Wasted Crawl Budget
Even though the recent crawl budget post covered the theory, logs give you the reality check you need. Look for patterns like:
- Repeated requests to low‑value pages (e.g., pagination URLs, session IDs, or tracking parameters).
- High frequency 404s that indicate broken internal links.
- Excessive requests to thin or duplicate content that dilutes your site’s overall value.
Once identified, you can consolidate pagination, add noindex tags, or implement proper canonical tags to guide crawlers toward the pages that truly matter.
Uncovering Indexing Issues Before They Escalate
Server logs surface indexing anomalies that might not appear in Search Console:
- Soft 404s – Pages returning a 200 status but with little or no content. Logs will show high bounce rates and short session times.
- Redirect chains – Multiple 301/302 hops that waste crawl budget and dilute link equity.
- Blocked resources – When robots.txt disallows essential JS or CSS, Googlebot may render the page incorrectly, leading to indexing errors.
By flagging these patterns early, you can clean up the site architecture and keep search engines happy.
Structured Data Errors: Seeing What Search Engines Miss
Even if you’ve rolled out schema markup across your product pages, a mis‑typed property can prevent rich results from appearing. Logs don’t directly show schema errors, but they do reveal when Googlebot requests the application/ld+json script and receives an unexpected HTTP status. Pair log analysis with a schema validator, and you’ll quickly pinpoint problematic pages that would otherwise slip through manual audits.
Core Web Vitals in the Server Log Context
Core Web Vitals are typically measured in the browser, but server logs give you a complementary perspective:
- Large
TTFB(time‑to‑first‑byte) spikes show up as higherresponse_timefields, indicating server‑side latency that can affect LCP. - Repeated slow responses for a specific asset (e.g., a large JS bundle) highlight opportunities for CDN optimization or asset compression.
When you combine log‑derived latency data with field data from Chrome User Experience Report (CrUX), you get a full‑stack view of performance bottlenecks.
Aligning Log Insights with Business Goals
Technical SEO isn’t an end in itself; it’s a lever for revenue‑generating outcomes. Map log‑derived metrics to key business KPIs:
- Lead‑gen pages – Ensure Googlebot crawls your pricing and demo request pages frequently, especially after a product update.
- Feature documentation – Monitor how often bots request your API docs; a dip could signal broken links or outdated references.
- Conversion funnels – Identify if any step in the funnel is being blocked by a 403 or 404, which can hurt both user experience and SEO.
By tying technical signals to revenue impact, you make a compelling case for continued investment in SEO infrastructure.
Tools & Automation: From Manual Queries to Real‑Time Alerts
Analyzing raw logs manually is akin to looking for a needle in a haystack. Fortunately, a robust ecosystem of tools exists:
- Logstash + Elasticsearch + Kibana (ELK) – Ingest, index, and visualize log data with custom dashboards.
- Splunk – Enterprise‑grade search and alerting, useful for large SaaS environments.
- Botify or Screaming Frog Log File Analyzer – Specialized SEO log‑analysis platforms that surface crawl issues with pre‑built reports.
Set up alerts for spikes in 5xx errors, sudden drops in crawl frequency for high‑value URLs, or abnormal increases in request latency. Real‑time notifications allow you to act before a ranking drop becomes noticeable.
Case Study: A SaaS Company Cuts Crawl Waste by 30%
Imagine a mid‑size SaaS platform with 12,000 pages of product documentation, blog posts, and user forums. After implementing a log‑analysis pipeline, the team discovered:
- Googlebot was spending 40% of its crawl budget on dynamically generated URLs with session parameters (e.g.,
?utm_source=mail). - Approximately 500 orphaned help‑center articles were never crawled because no internal links pointed to them.
- A handful of 301 redirect chains caused a 2‑second delay in reaching the final destination.
By normalizing URL parameters, adding canonical tags, and fixing redirect chains, the site reduced wasted crawl budget by 30% and saw a 12% uplift in organic traffic to conversion‑critical pages within two months.
Best‑Practice Checklist for Server‑Log‑Driven SEO
- Centralize logs from all servers, CDNs, and load balancers.
- Filter by bot user‑agents (Googlebot, Bingbot, etc.) and isolate human traffic.
- Identify high‑frequency 404s and map them to missing internal links.
- Detect redirect chains and consolidate them into single‑step 301s.
- Monitor response times for key assets to pre‑empt Core Web Vitals issues.
- Cross‑reference log findings with Search Console, CrUX, and structured‑data testing tools.
- Automate alerts for spikes in error rates or latency.
- Document changes and track impact on crawl patterns and traffic.
Integrating Log Analysis with Broader SEO Strategies
Server‑log insights don’t exist in a vacuum. Pair them with other technical initiatives for maximum effect:
- Edge SEO – Use edge servers to serve static assets faster, then confirm via logs that latency drops are reflected in real‑world request times.
- Privacy‑First SEO – Ensure that privacy‑compliant headers (e.g.,
Content‑Security‑Policy) don’t inadvertently block crawlers, a problem you can catch in the logs. - Content audits – When logs show certain pages receiving little to no crawl activity, prioritize them for content refresh or removal.
Final Thoughts: From Data to Action
Technical SEO is often described as “the science of making it easy for search engines to understand your site.” Server logs are the raw data that turn that science into an art. By regularly mining logs, you gain a continuous feedback loop that uncovers hidden bugs, optimizes crawl efficiency, and aligns SEO performance with business objectives. The next time you’re tempted to rely solely on dashboards, remember that the most truthful story about your site is written line‑by‑line in the server log.
Kelly Reynolds is a dynamic freelance writer hailing from the picturesque landscapes of Alberta. A master of the written word, she juggles her passion for storytelling with the exhilarating chaos of being a mother to five spirited children. With an impressive portfolio that spans various genres, Kelly captivates readers through her engaging blog posts and thought-provoking articles.
Related Posts
Crawl Budget Mastery: How SaaS Companies Can Get Google to Index What Matters
Discover why crawl budget is a hidden growth lever for SaaS, and follow a step‑by‑step guide to ... Read More
Edge‑First Technical SEO: Leveraging CDNs and Serverless for SaaS Rankings
Discover how a edge‑first approach—using CDNs, serverless functions, and the latest HTTP protoco... Read More
Server‑Side Rendering: The Technical SEO Game‑Changer for JavaScript‑Heavy Sites
Learn why Server‑Side Rendering is essential for modern JavaScript sites, how to implement it with... Read More
Top Posts
Privacy‑First Marketing: Thriving in a Cookieless World
Learn to turn privacy constraints into creative opportunities, using first‑party data, contextual targeting, and transparent practices to boost engagement and...Read More
Dynamic Pricing Powered by Real‑Time Data: A Game‑Changer for eCommerce
Learn why static prices limit growth and how real‑time dynamic pricing, backed by data and AI, can boost margins, improve inventory flow, and keep shoppers lo...Read More
Mastering Crawl Budget: The Silent Engine Behind Google Algorithm Success
Discover why crawl budget matters, practical steps to optimize it, and how to future‑proof your site against Google's evolving algorithm....Read More
Turn Your SaaS Onboarding Flow Into an SEO Engine
Learn to leverage your SaaS onboarding flow—emails, tutorials, videos, and help‑center articles—as powerful SEO assets, driving high‑intent traffic and ...Read More
0 Comments
Post Comment
You will need to Login or Register to comment on this post!